How to fix text to speech accuracy problems
- Written by
- Jack Limebear
- Published
ListenListen to this article
While they’re trained on massive voice datasets and can consistently produce high-fidelity audio, most text to speech (TTS) models can still mispronounce words or run into other speech issues. Mispronunciations happen when a TTS engine encounters words and phrases outside the range of speech in its training dataset. That happens most often with industry jargon, brand names, or proper names.
TTS engines may also generate rushed, stilted, or robotic speech when text passages are long or punctuated for reading rather than structured to be spoken out loud.
You may also encounter a few common technical issues connecting your applications to TTS engines via API.
In this article, we’ll explore these three categories of issues and common ways to resolve each.
Summary
- Text to speech failures generally fall into the categories of vocal mispronunciations, unnatural pacing/cadence, and technical API execution errors.
- You can fix mispronunciations most effectively with W3C-standard Pronunciation Lexicon Specification (PLS) dictionaries or adjust them individually using phonetic tags in-line in your scripts.
- You can help control the naturalness of your speech output by formatting and punctuating your script appropriately. Text formatted for speaking often differs from text intended only to be read.
- You can diagnose API failures via standard HTTP status codes.
- Upfront testing for the pronunciation of brand names, proper names, and novel phrases in isolation can save you extensive troubleshooting after the fact.
Why is text to speech not working?
Text to speech problems broadly fall into three categories.
TTS problem types
Mispronunciations
The TTS model misreads novel words or phrases. e.g., your brand name, industry jargon, acronyms, or homographs.
Unnatural delivery & cadence
The output speech is monotonous, pauses at odd points, or rushes through passages that need slower delivery.
Integration & API failures
Your application doesn’t generate speech for one or more technical reasons, such as missed voice IDs, workload limits, or broken API keys.
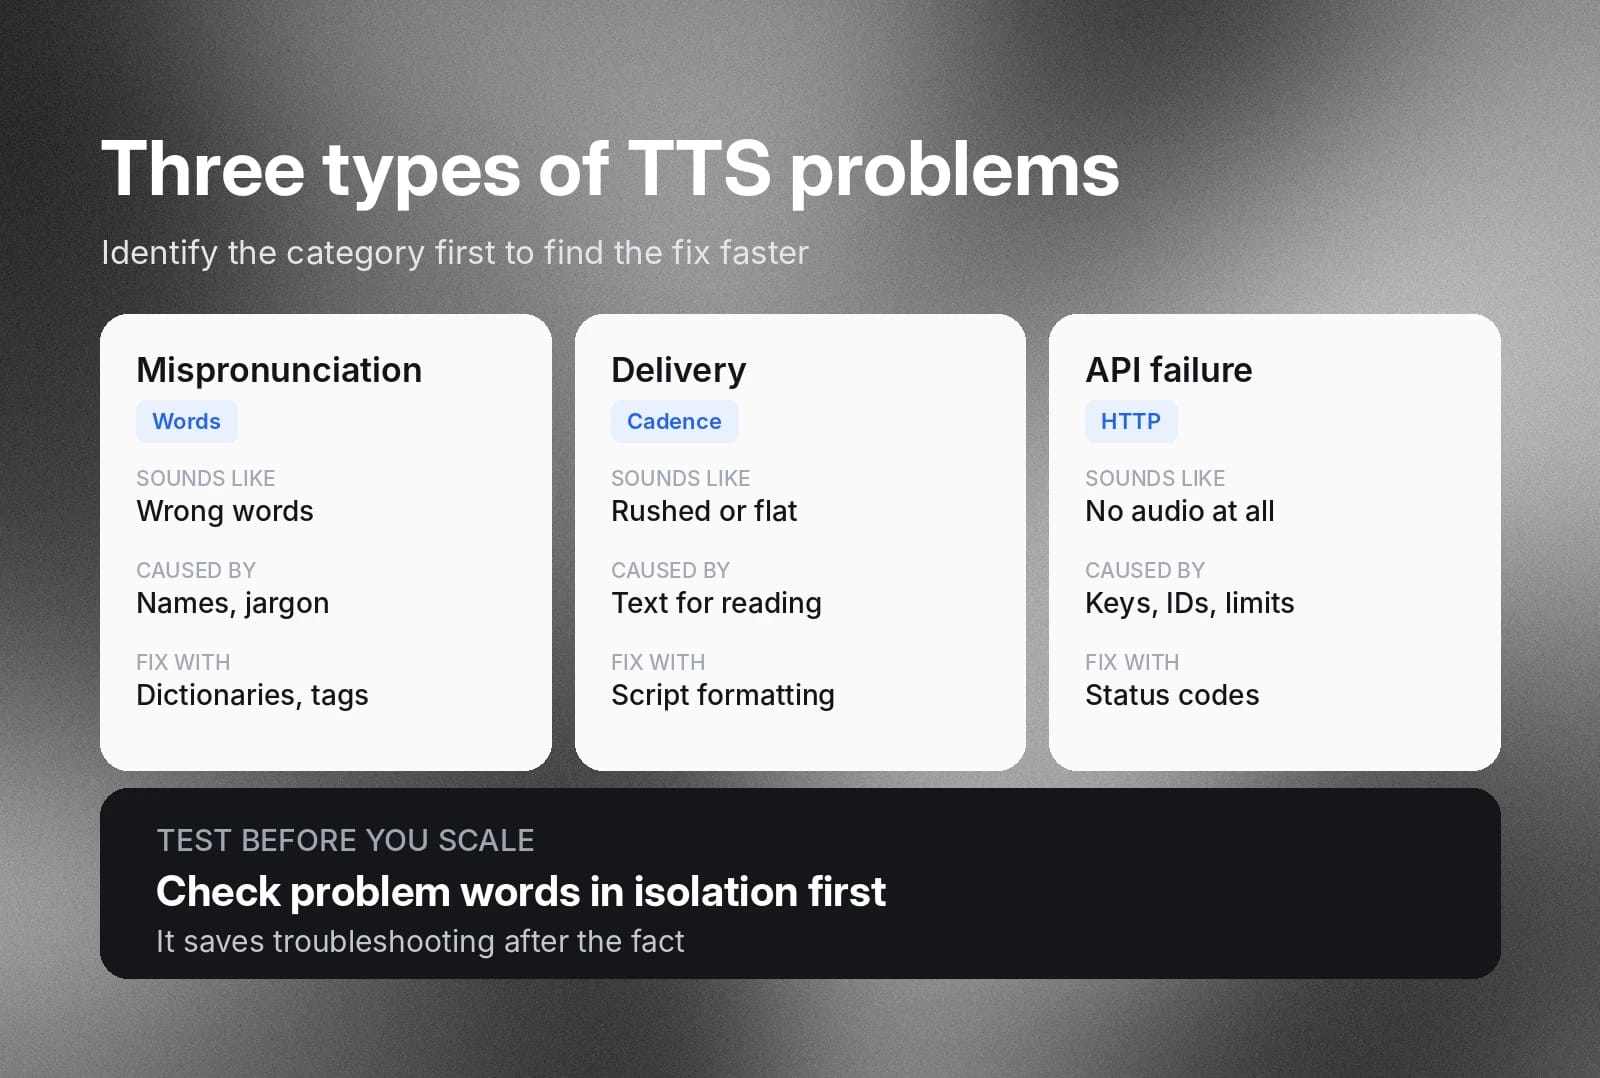
This guide breaks down each of these three issues in more detail so you can understand exactly what kind of output quality or technical issue you’re facing. Understanding them will help you identify the right solution faster.
How to fix text to speech accuracy problems: Mispronunciation and unnatural delivery
Engineers train modern neural voice models on massive speech datasets. They’re able to generate natural-sounding speech in almost countless combinations of words. However, no training dataset is ever universal. There are always going to be edge-case pronunciations and obscure words or proper names the model won’t speak correctly.
This won’t happen often, but everyone who uses TTS models regularly should be prepared for how to handle it when it happens. First, it’s important to understand why these mispronunciations occur.
Common root causes of speech errors
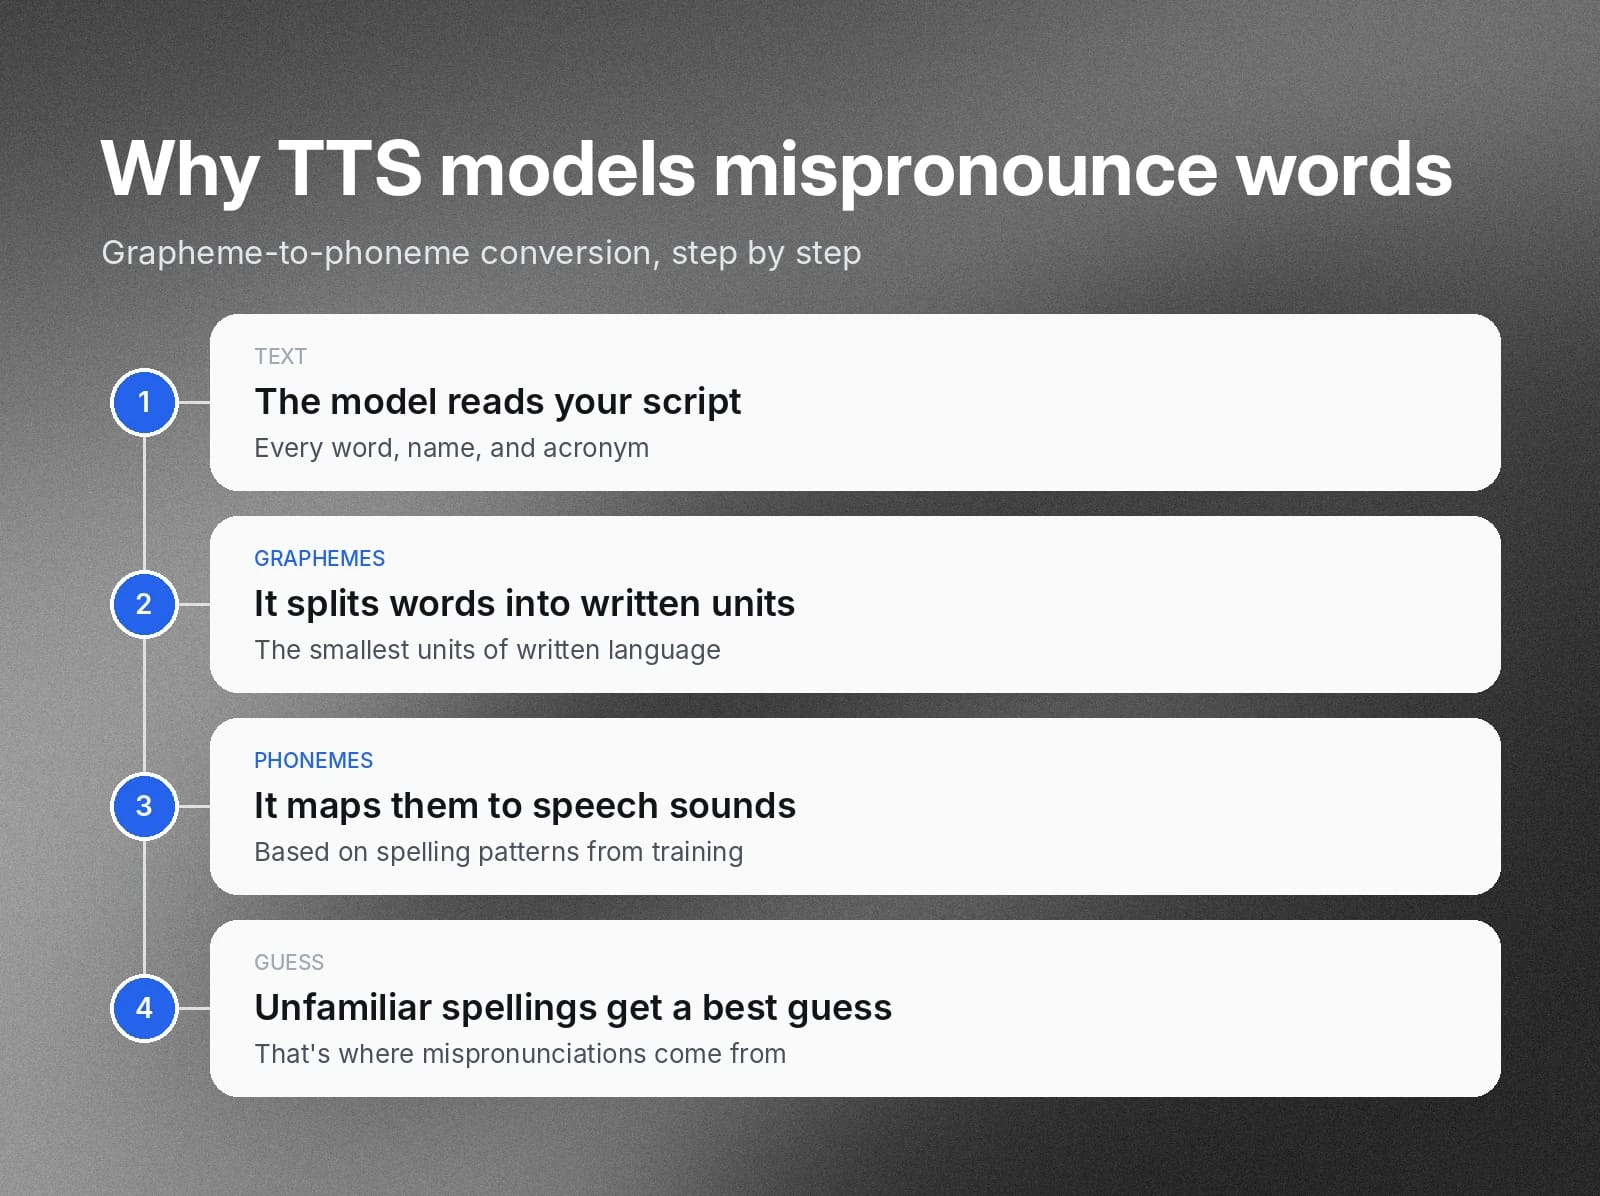
Speech synthesis models work by converting text into speech using a process called grapheme-to-phoneme (G2P) conversion. Phonemes are the smallest units of spoken sound. Graphemes are the smallest units of written language, typically one letter, that represent a phoneme.
When text input doesn’t match the spelling patterns the models encountered in training data, they take their best guess as to the phonetic pronunciation. Sometimes this leads to mispronunciations.
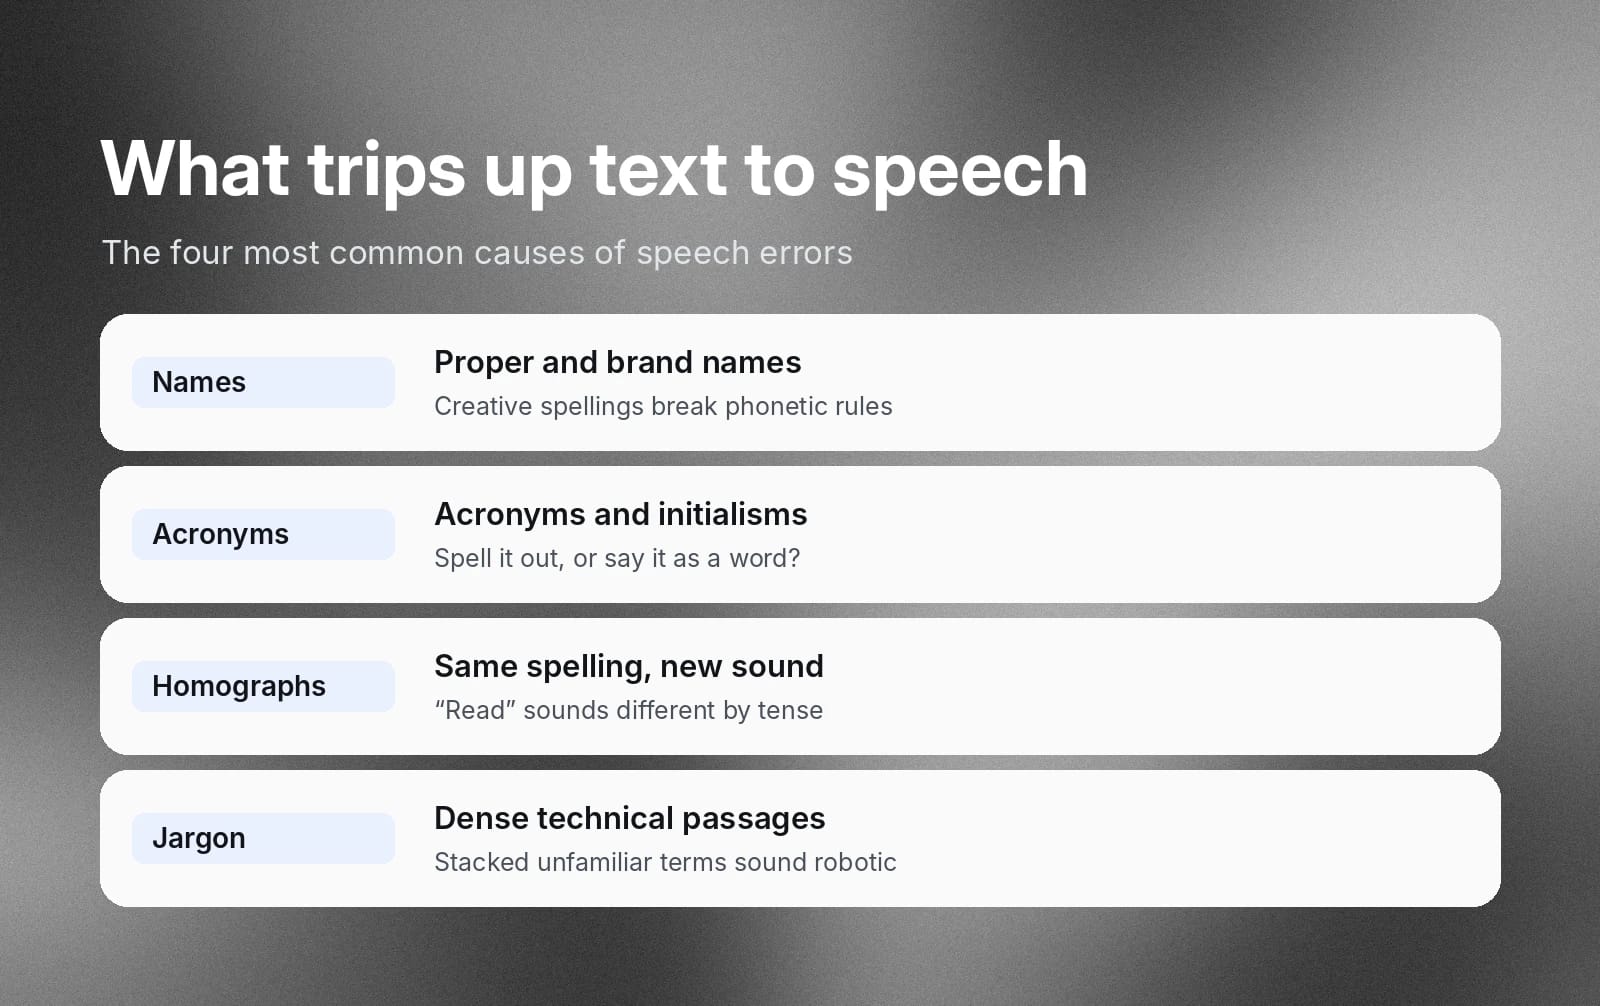
Proper names and brand names
Businesses often use creative spellings for brand names. They catch the eye, but often also confound speech synthesis models. Creative first names and surnames can as well, for the same reason.
When a model encounters an unfamiliar name, it tries to apply the basic phonetic rules it learned. That output speech might be far off from what you want.
Acronyms & initialisms
Think about the acronym NASA. Imagine you’ve never seen it before, much like a speech model might. Do you pronounce it “N.A.S.A.” or “nasuh?” What about a software API? Is that “A.P.I.” or “apee?” What if your company is selling a brand new software tool with a new acronym? You can guarantee it’s not in a speech model’s training data. So the model would have to guess how you wanted it pronounced unless you gave it custom instructions.
Homographs
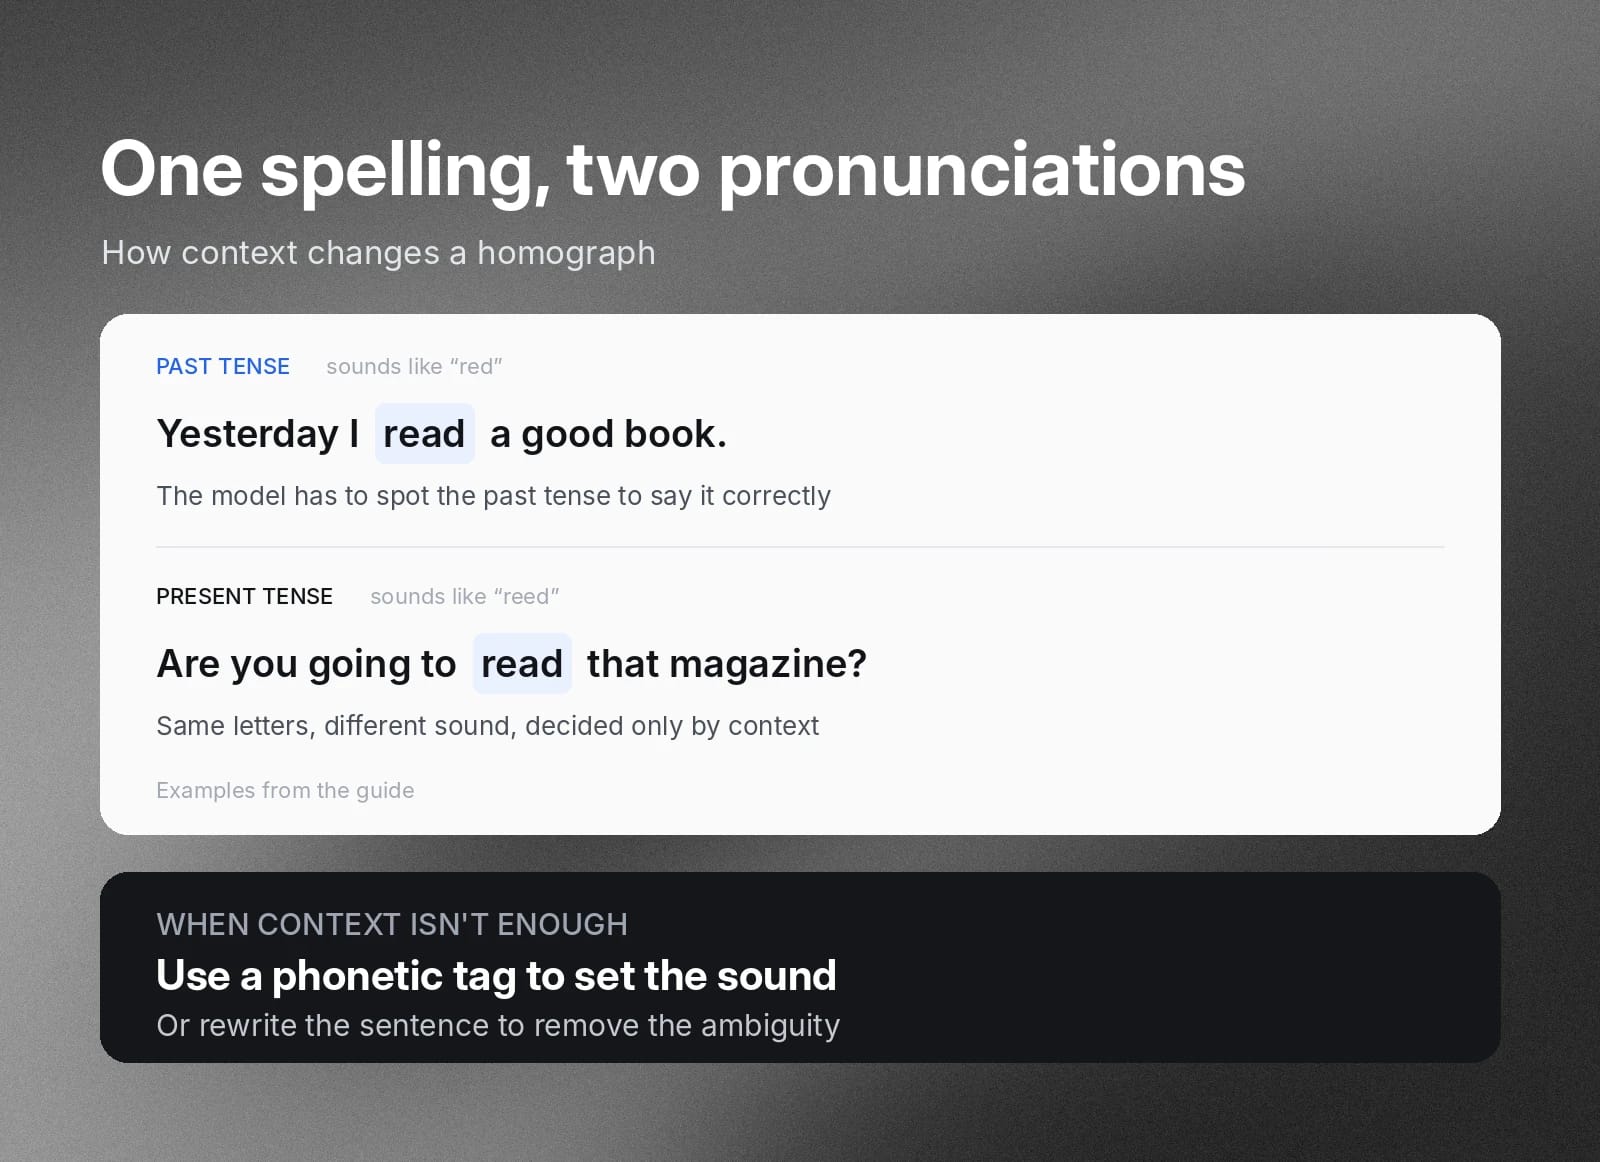
Homographs are words that share spellings but have different pronunciations depending on context. For example, the word “read” is spelled the same but pronounced differently in the past and present tenses.
- “Yesterday I read a good book.”
- “Are you going to read that magazine?”
A speech model will need sufficient contextual understanding to determine how to pronounce homographs as you wish.
Unnatural stress patterns
Long sentences of technical jargon can pile obscure words on top of specific pronunciations and acronyms in short order. What might be an unnoticeable error by itself can quickly become part of flat, robotic speech as a model tries to parse many unfamiliar words and phrasings.
Two ways to control voice pronunciation
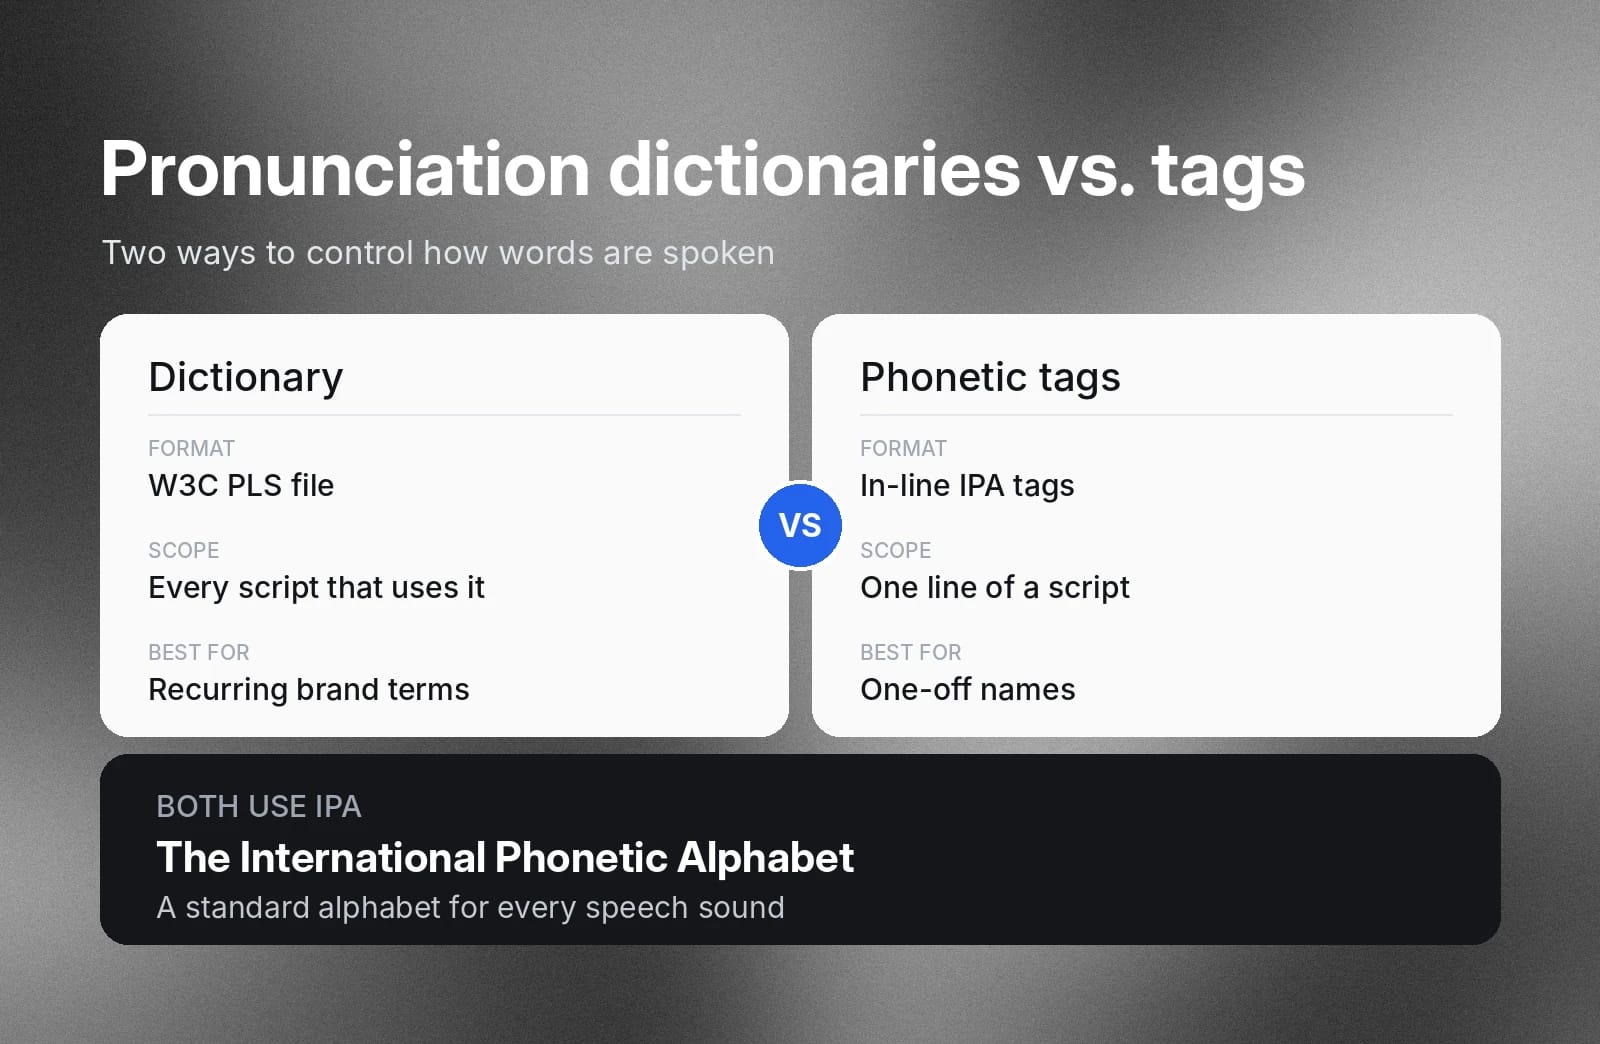
You don’t need to completely rewrite your scripts to avoid these scenarios. Modern neural speech models include two tools to fix them efficiently, case by case: pronunciation dictionaries and phonetic script tags.
Text to speech pronunciation dictionaries
Dictionaries are best when you have a body of custom pronunciations that recur regularly across your TTS projects. For example, if your company sells medical devices and your scripts regularly contain technical terms, medical procedures, and other domain-specific content.
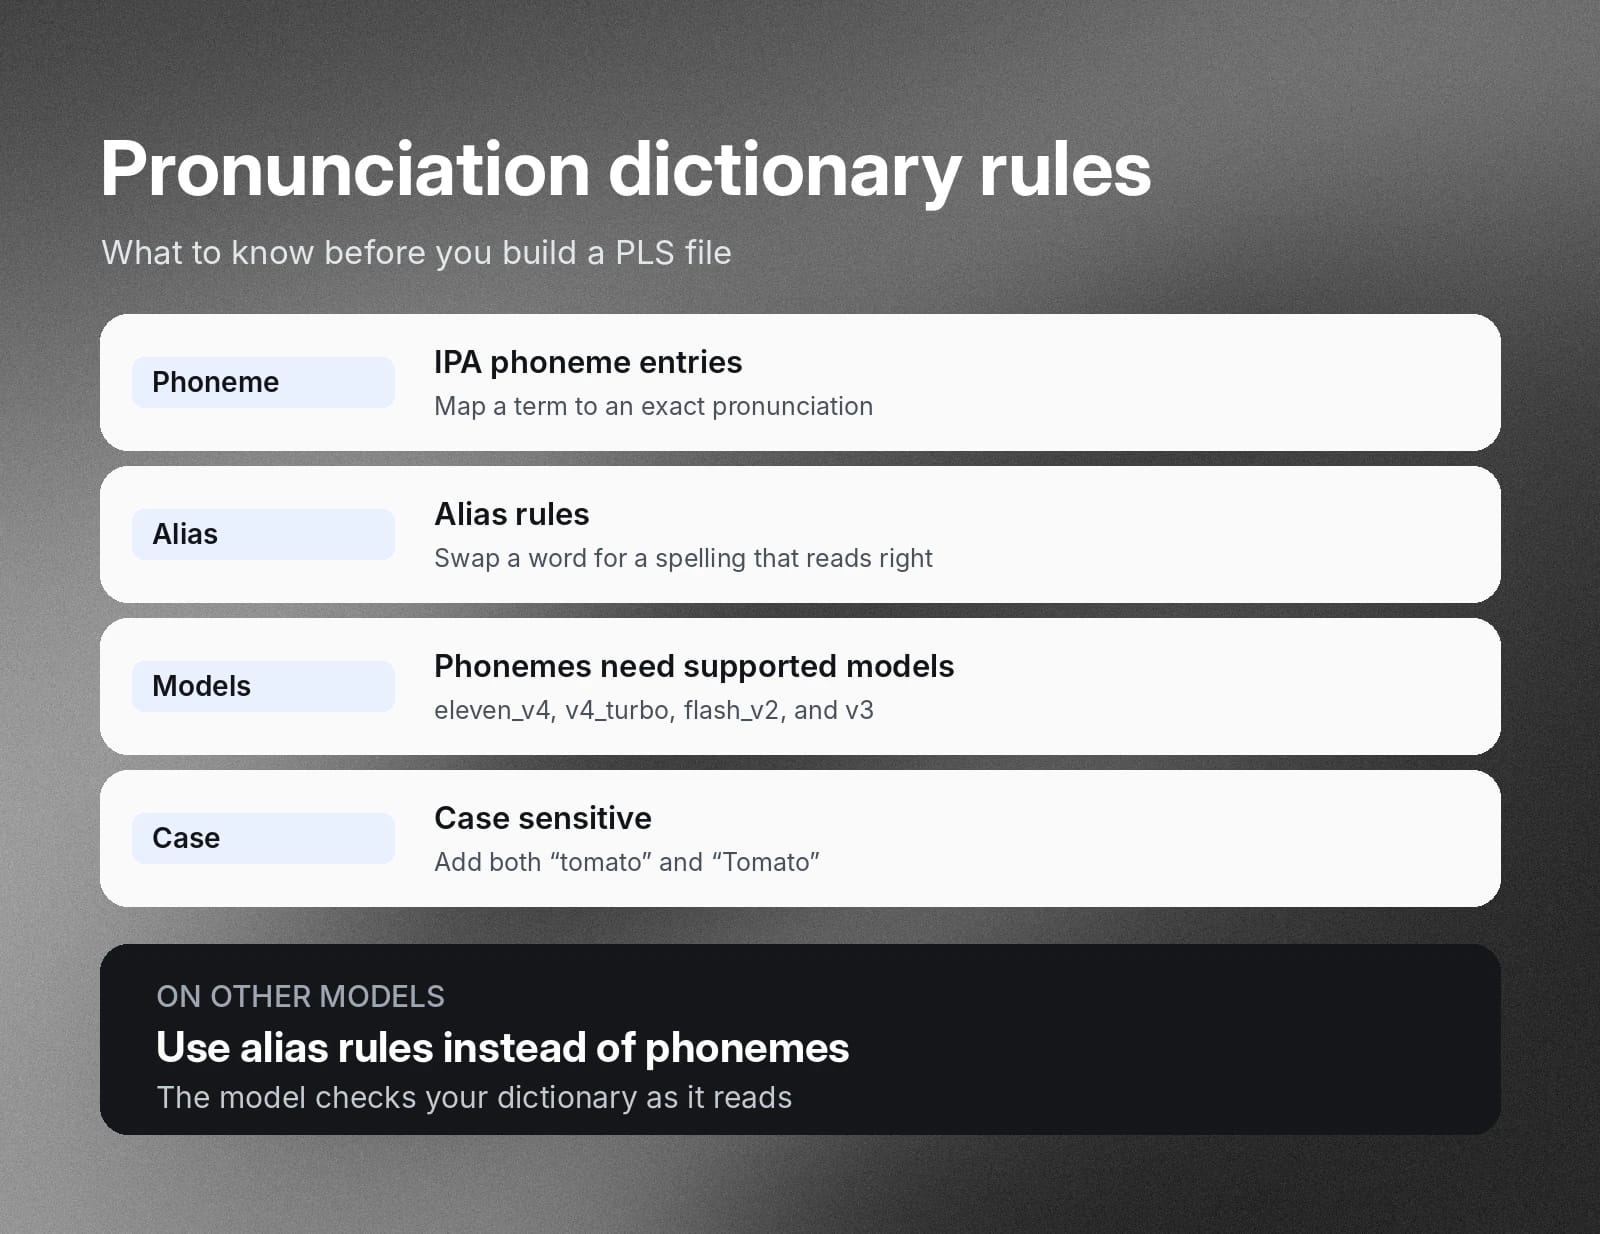
The W3C-standard Pronunciation Lexicon Specification (PLS) format provides a structure for mapping those terms to specific phonetic pronunciations using International Phonetic Alphabet (IPA) notation. The International Phonetic Alphabet is a standardized alphabet of all possible speech sounds. The speech model checks your dictionary as it reads the script and refers to your listed pronunciations whenever it encounters words in your dictionary. Phoneme entries work only with the eleven_v4, eleven_v4_turbo, eleven_flash_v2, and eleven_v3 models. On other models, use alias rules instead. PLS files are case sensitive, so add both “tomato” and “Tomato” if you need both.
Phonetic script tags
Phonetic tags are usually the better choice when you need to tweak single lines in a script. Rather than generating a dictionary, you use in-line phonetic tags that prompt the speech model to say a word how you want according to the IPA.
For example, let’s say you’re writing a podcast script and you want to reference an industry expert two or three times. Instead of adding it to your corporate pronunciation dictionary, you just tag her name with the correct pronunciation when you use it in the script.
Write and format scripts that sound natural when spoken aloud
Dictionaries and tags are useful for managing issues with individual words in speech output, but they don’t address overall delivery, cadence, and speech dynamics. When writing a script, it’s important to frame your text with the understanding that it’s going to be spoken aloud. Your word choices, turns of phrase, and punctuation often should be different from that of text meant simply to be read.
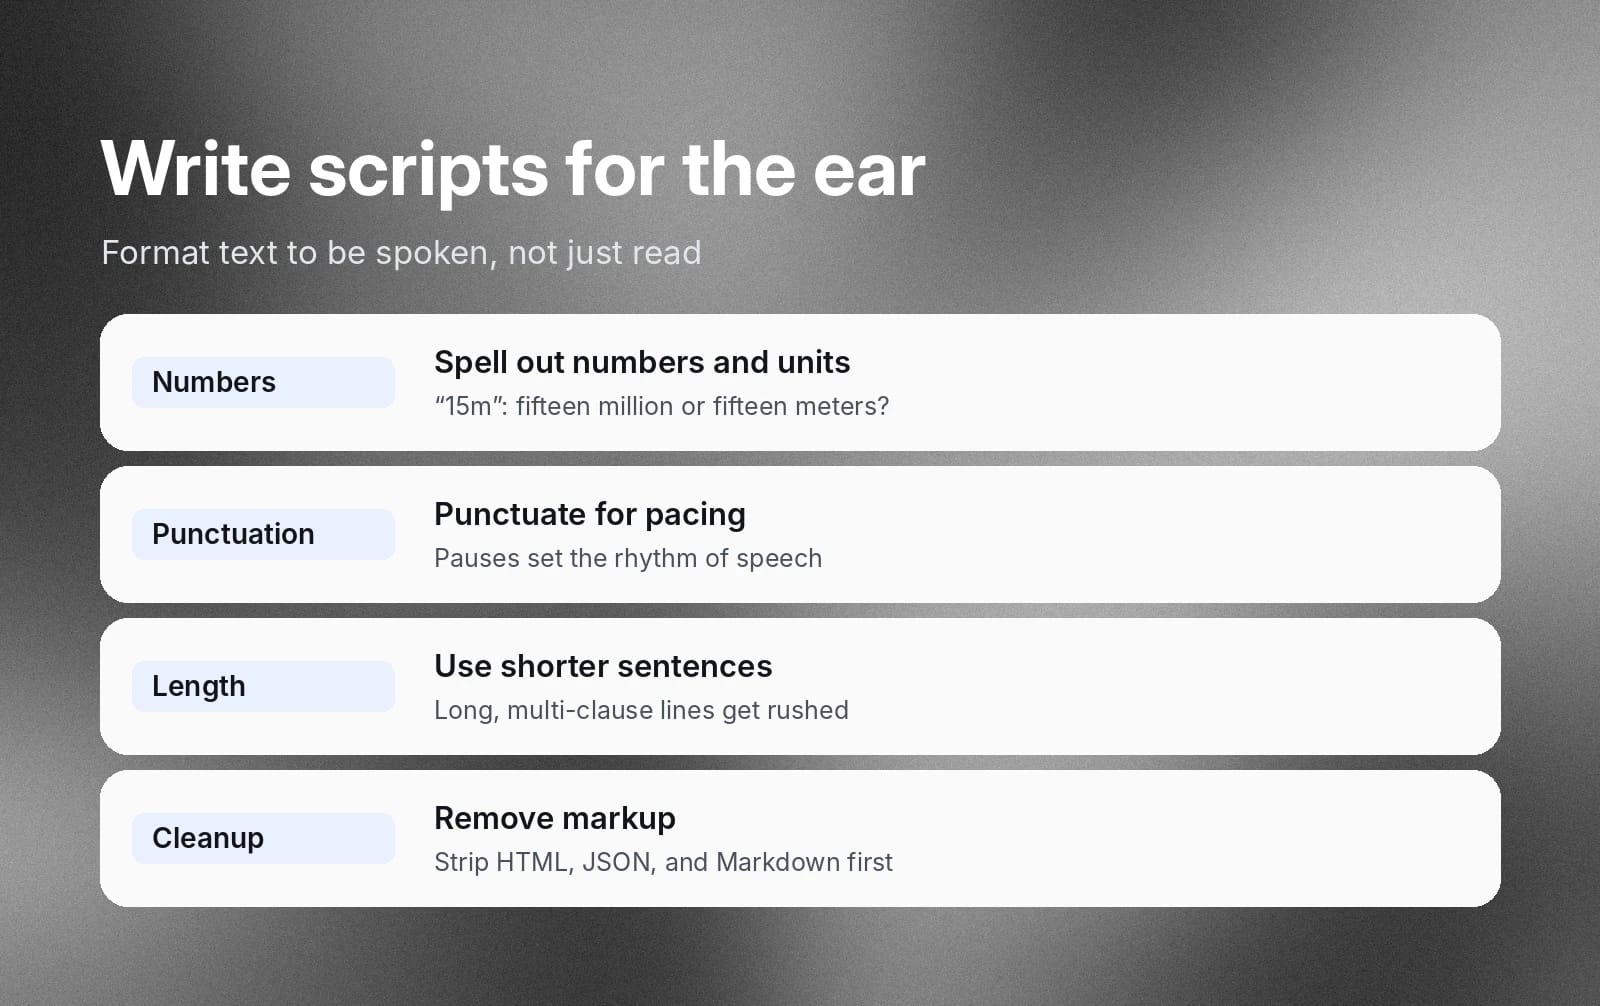
Write for the ear, not the eye
Approach your script writing with the mindset of a speech writer: “How do I want this spoken aloud? Where do we pause for dramatic effect? Where do we speed up?” Those questions apply to a script for advanced neural speech models just as much as to a script you’d write for a person.
Spell out numbers, currencies, and dates
You don’t want to leave any ambiguity in your scripts. Neural speech models understand context well, but they perform best when they don’t have to guess. Abbreviations and shorthand are common items they might stumble over.
For example, a script might say, “You’re looking for a figure close to 15m.” Does the writer want the TTS engine to say “fifteen million” or “fifteen meters?” Write it out so the model doesn’t have to guess from context.
Use regular punctuation to control pacing
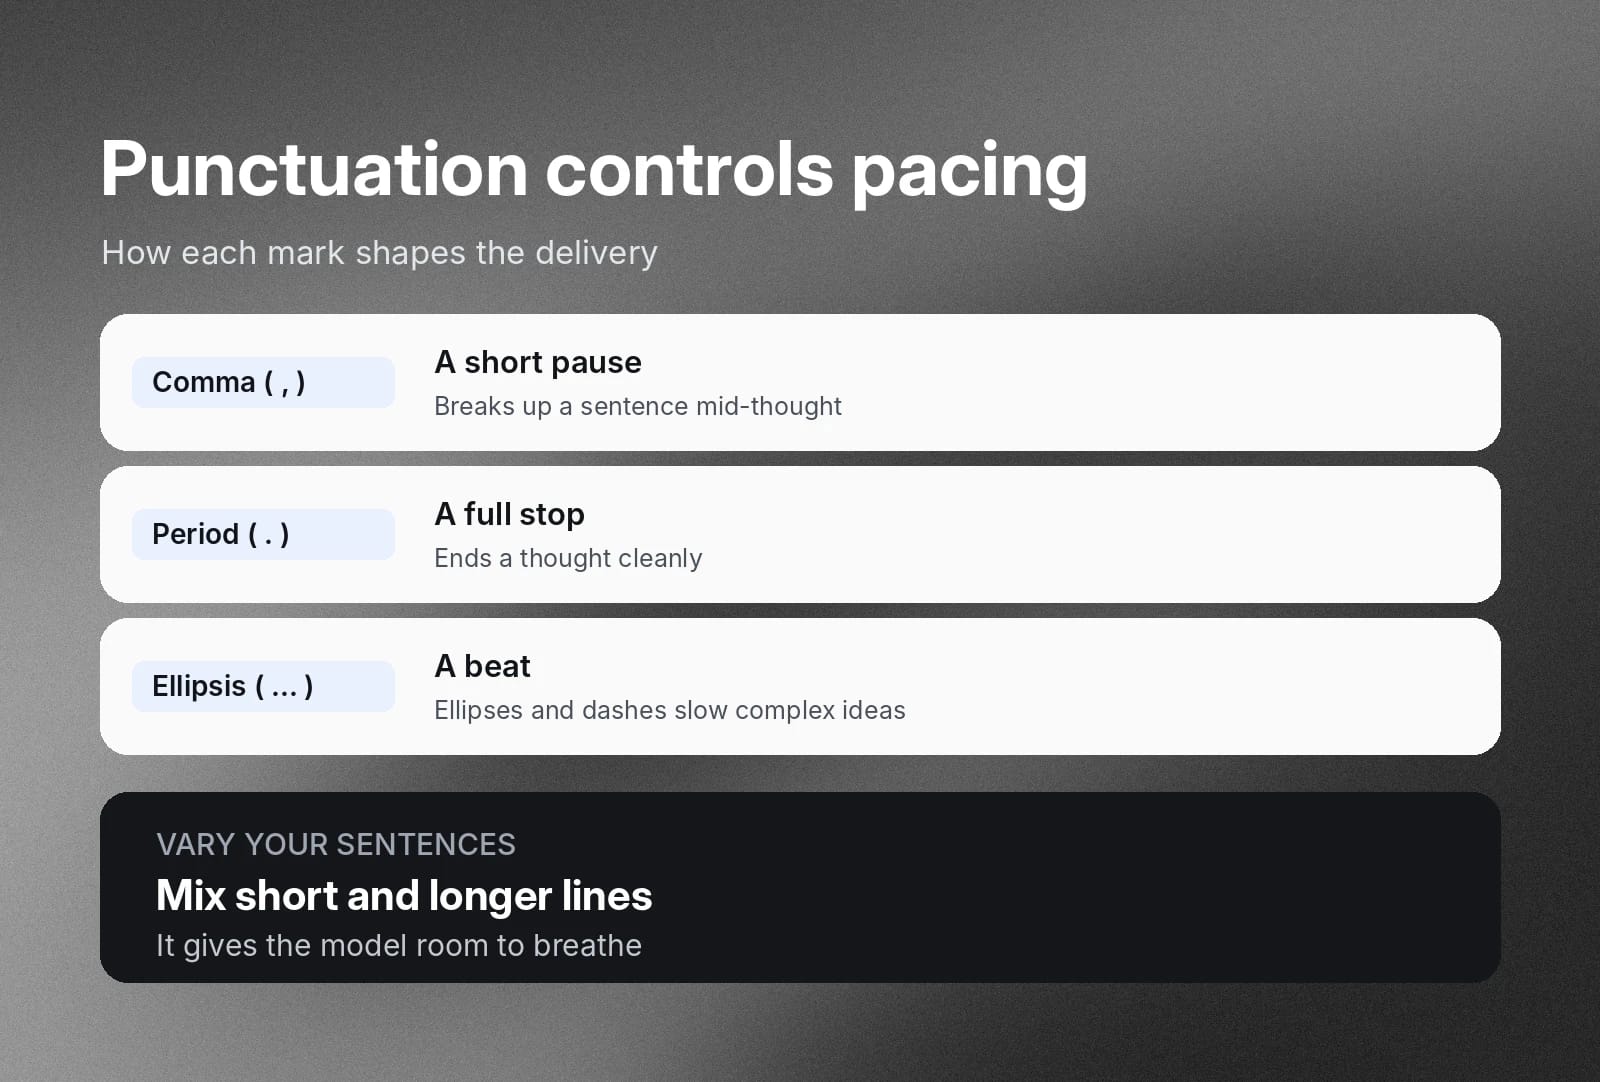
Punctuation plays an important role in written text, but it matters even more in text to speech synthesis. Punctuation controls the rhythm. It represents different types of pauses you can use to break up complex thoughts or simply to maintain a natural cadence that’s more comfortable for someone to listen to.
- Use commas for short pauses mid-sentence.
- Use periods as a full stop to end a thought.
- Use ellipses and em dashes to add a beat in the middle of complex ideas so your model doesn’t sound rushed.
Short sentences are better sentences
Models are most likely to stumble over or rush long, conditional, multi-clause sentences. Break those apart into shorter statements of varied length. This gives the model more breathing room and prevents it from rushing when it tries to find the cadence for long, run-on sentences.
Remove formatting and markdown artifacts
If you’re synthesizing speech pulled from a content management system or other business system, it might contain HTML, JSON, Markdown, or other formatting. Remove this and format it as text to get the most natural-sounding speech. Speech models may struggle to understand when to ignore those tags, read them literally, or incorporate them contextually into their output.
You can explore mispronunciation and other issues more at length in the ElevenLabs troubleshooting guide.
Fix common ElevenLabs API errors
Teams that produce voice audio at scale typically connect their applications to a speech synthesis model by API. This makes production more efficient overall, but it adds a technical layer you need to manage on top of the model's speech output.
The ElevenLabs API error code reference covers response codes in detail, but here are the four most common HTTP status codes encountered when troubleshooting text to speech integrations, and how to address them.
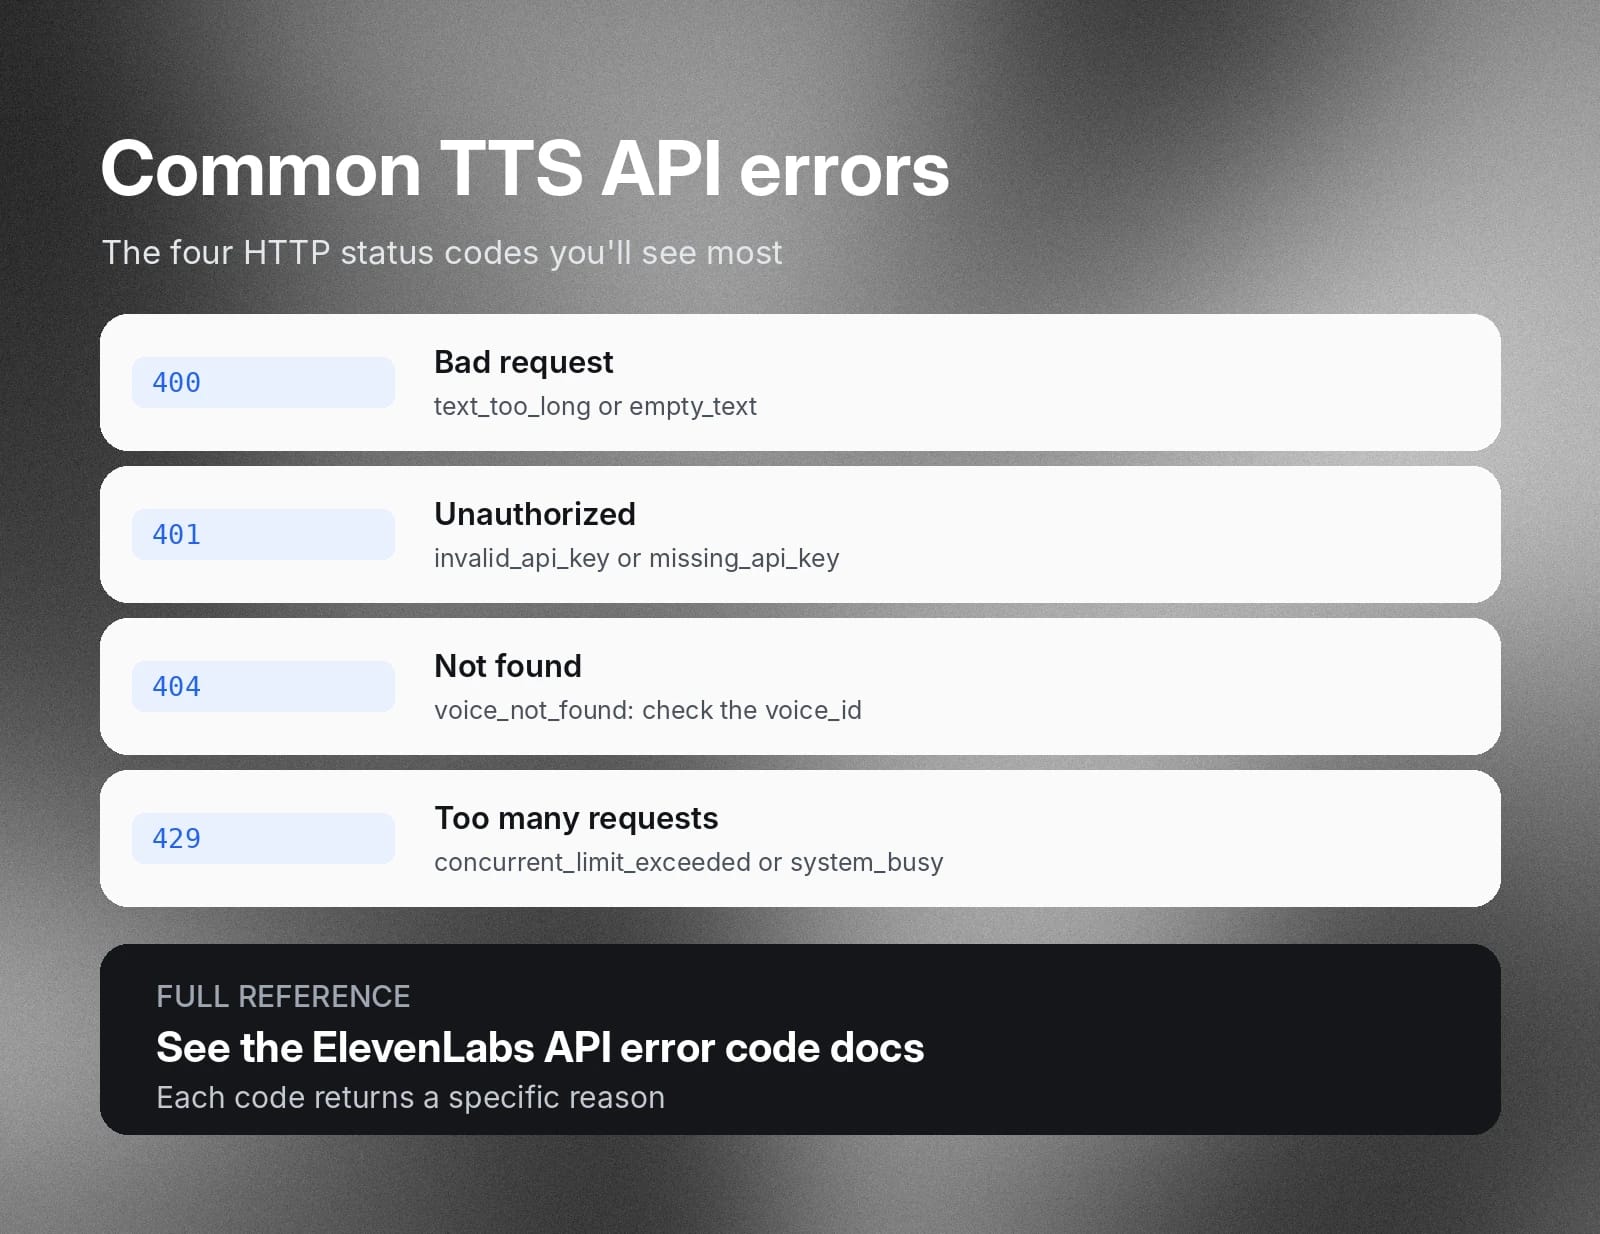
400 Bad Request (Payload errors)
A 400 status code response from a speech model API means your application sent data the model couldn’t process. In TTS workflows, that typically stems from hitting character limits or accidentally sending blank inputs.
Character limit exceeded (text_too_long)
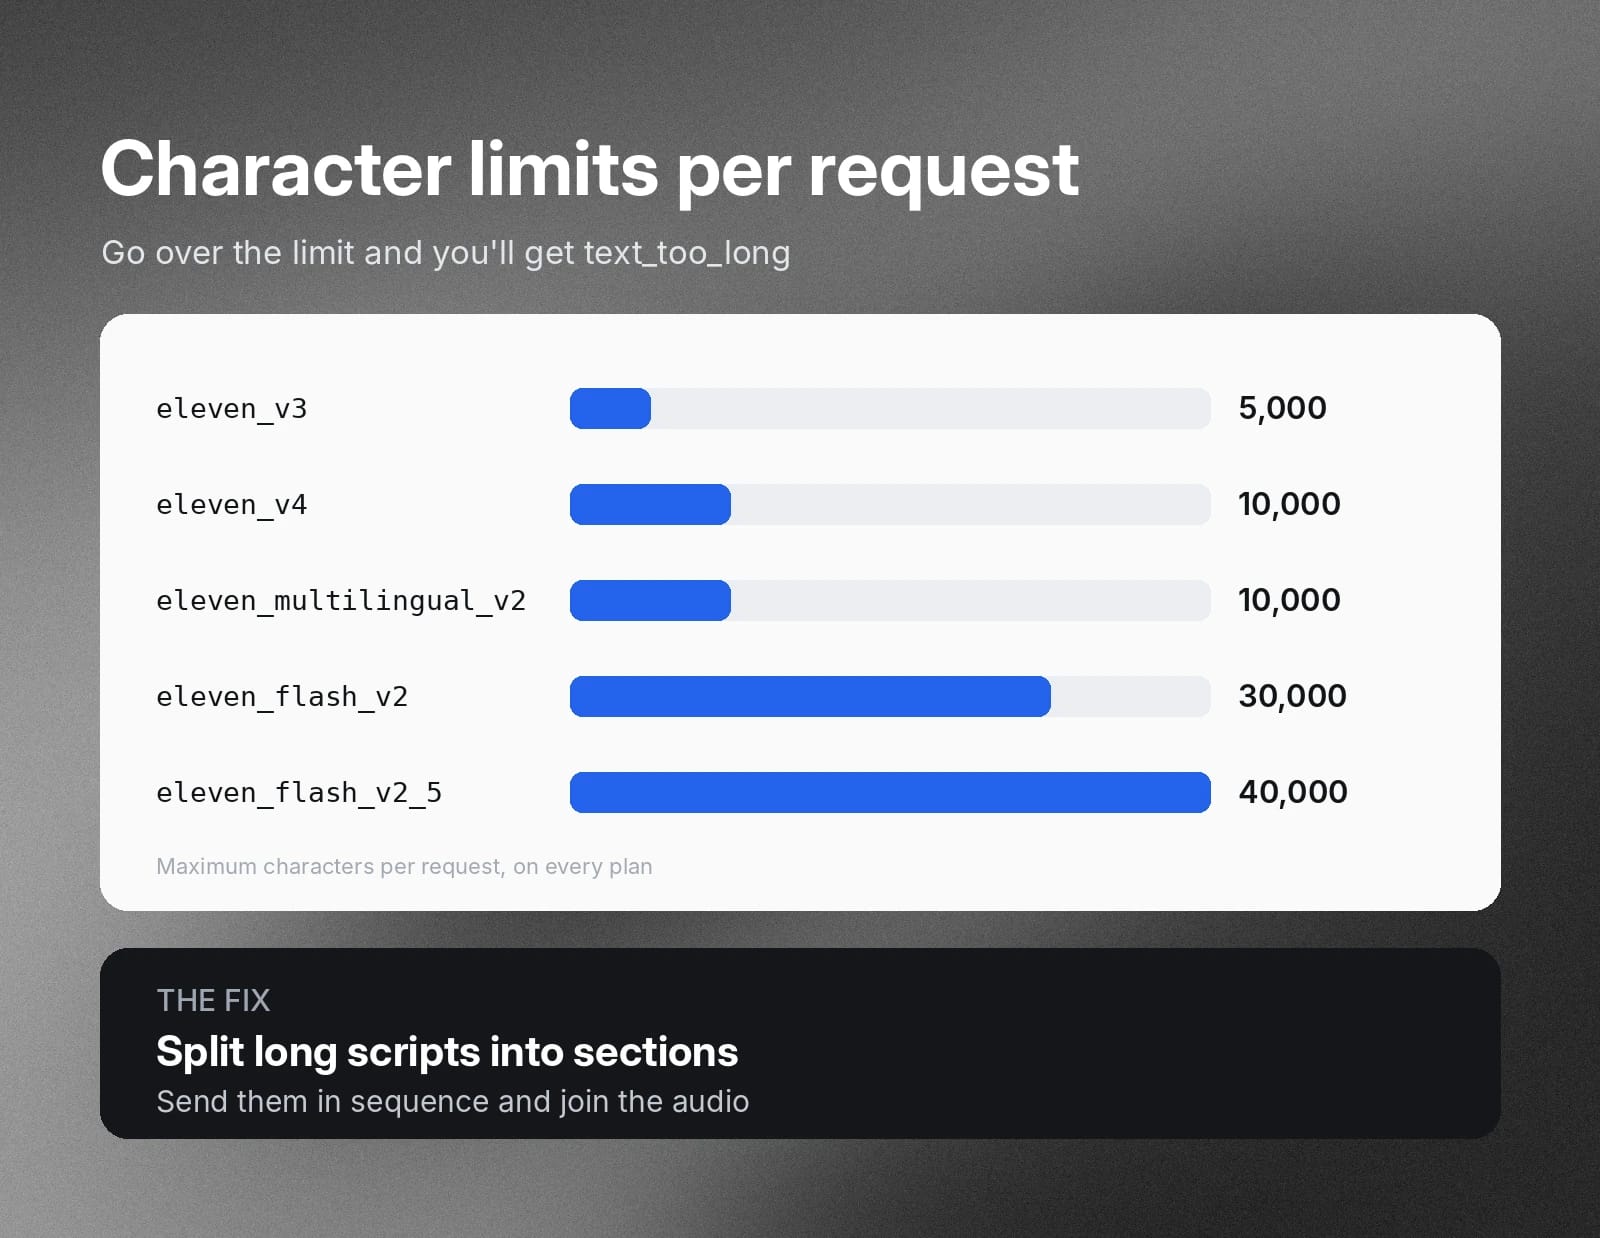
Every TTS request you send has a character limit set by the model. If you try sending more text than the model’s limit allows, the TTS server will return this error. Limits per request are 10,000 characters for eleven_v4 and eleven_multilingual_v2, 5,000 for eleven_v3, 30,000 for eleven_flash_v2, and 40,000 for eleven_flash_v2_5, on every plan. To resolve this issue, split longer scripts into multiple sections the model can process sequentially.
Empty input text
A TTS engine will reject any payloads that contain empty strings (empty_text). Include cleaning steps in your input pipeline to remove empty lines so the server doesn’t reject an otherwise workable payload.
401 Unauthorized (Authentication issues)
A 401 error code means the API gateway rejected your credentials and your payload wasn’t passed to the model. This happens when there’s an issue with the API key.
Invalid API key
Your request to the model server needs to include a valid xi-api-key. If it doesn’t, the server will return a 401 error. Verify that your key is actually present in the request and hasn’t been revoked, expired, or truncated from headers in deployment. The API returns invalid_api_key when the key is wrong and missing_api_key when none is sent.
404 Not Found (Voice identifier mismatches)
You receive a 404 error when the endpoint can’t find the TTS resource specified in the URL request. This might occur if you send the wrong voice_id parameter or it’s just missing from the request URL. Make sure you’ve received the correct voice_id to use. Verify it’s actually present in the path parameters and not mistyped. The API returns voice_not_found when the voice ID doesn’t exist.
429 Too Many Requests
This error has two distinct causes: you’ve hit your concurrent request limit for your service tier or the TTS platform is throttling requests to manage a spike in traffic.
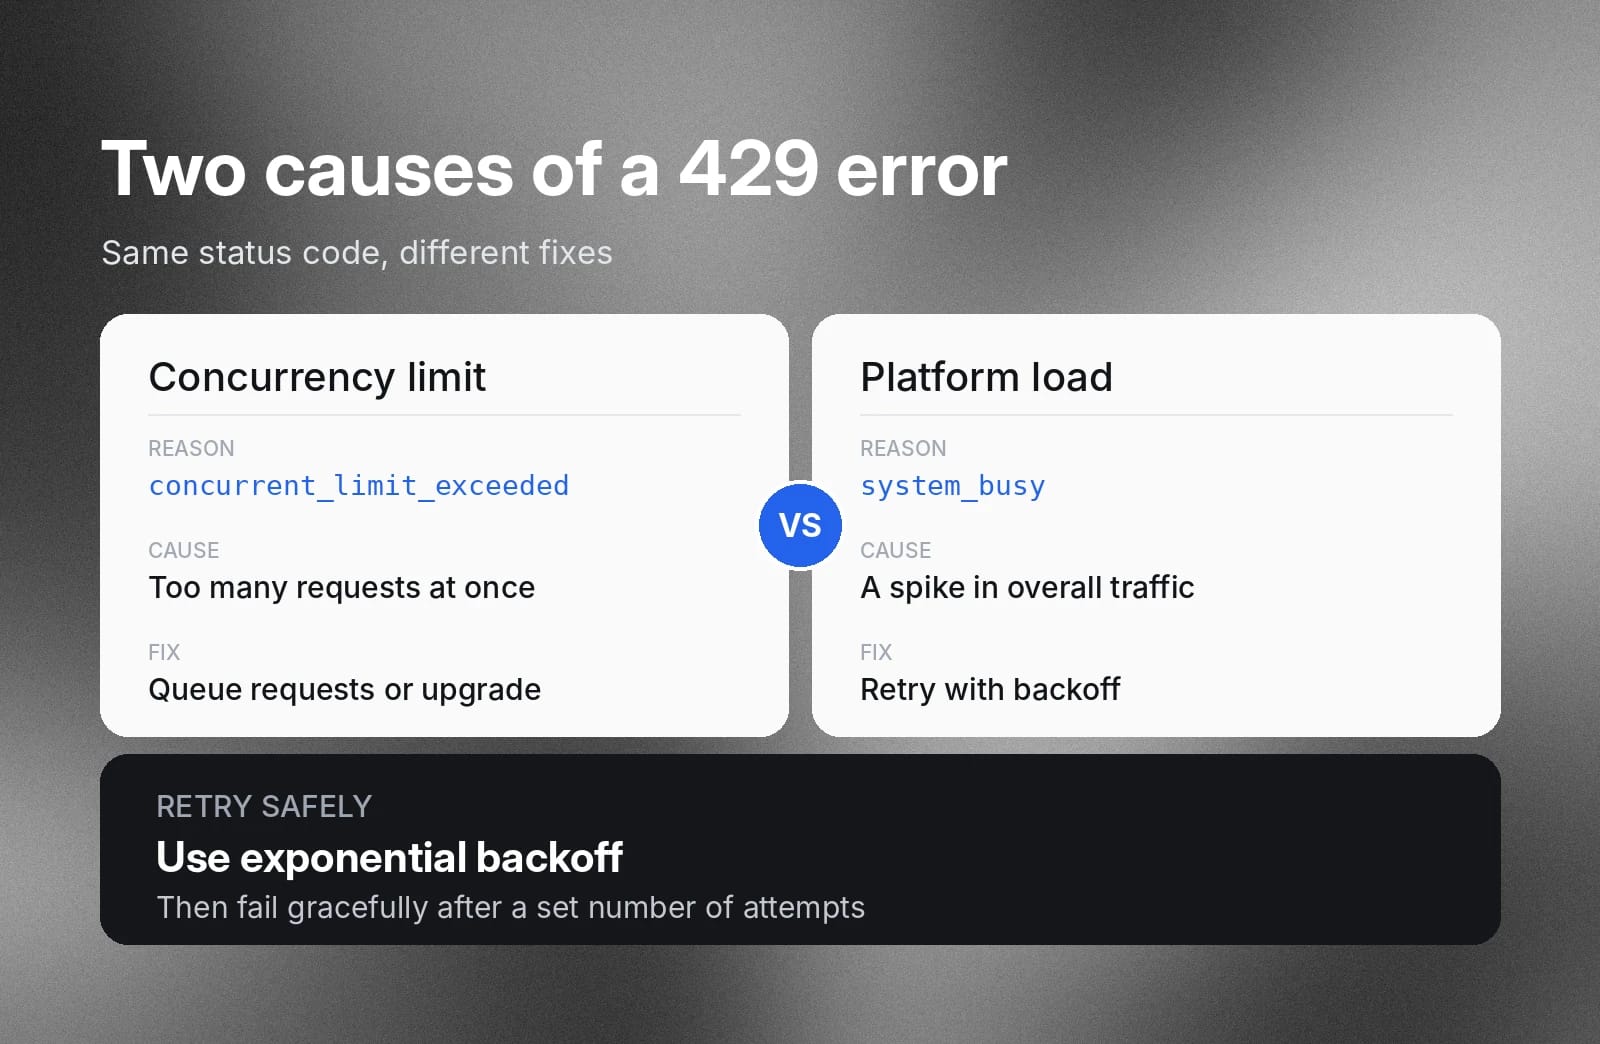
Concurrency limits (concurrent_limit_exceeded)
Each subscription tier to a TTS engine specifies a fixed number of concurrent requests you can send. If your applications exceed that limit, the server will return this type of 429 error.
Build an asynchronous queuing layer using a service such as Redis to meter your outgoing payloads so they don’t exceed your tier limits. Or assess whether a higher tier subscription is cost-effective.
Platform load spikes (system_busy)
Under heavy load, a TTS server may throttle incoming requests to maintain performance. Build automated retry logic into your application’s API client. Make sure it can retry with exponential backoff and then fail gracefully after a maximum number of attempts.
Test voices, languages, and settings before publishing
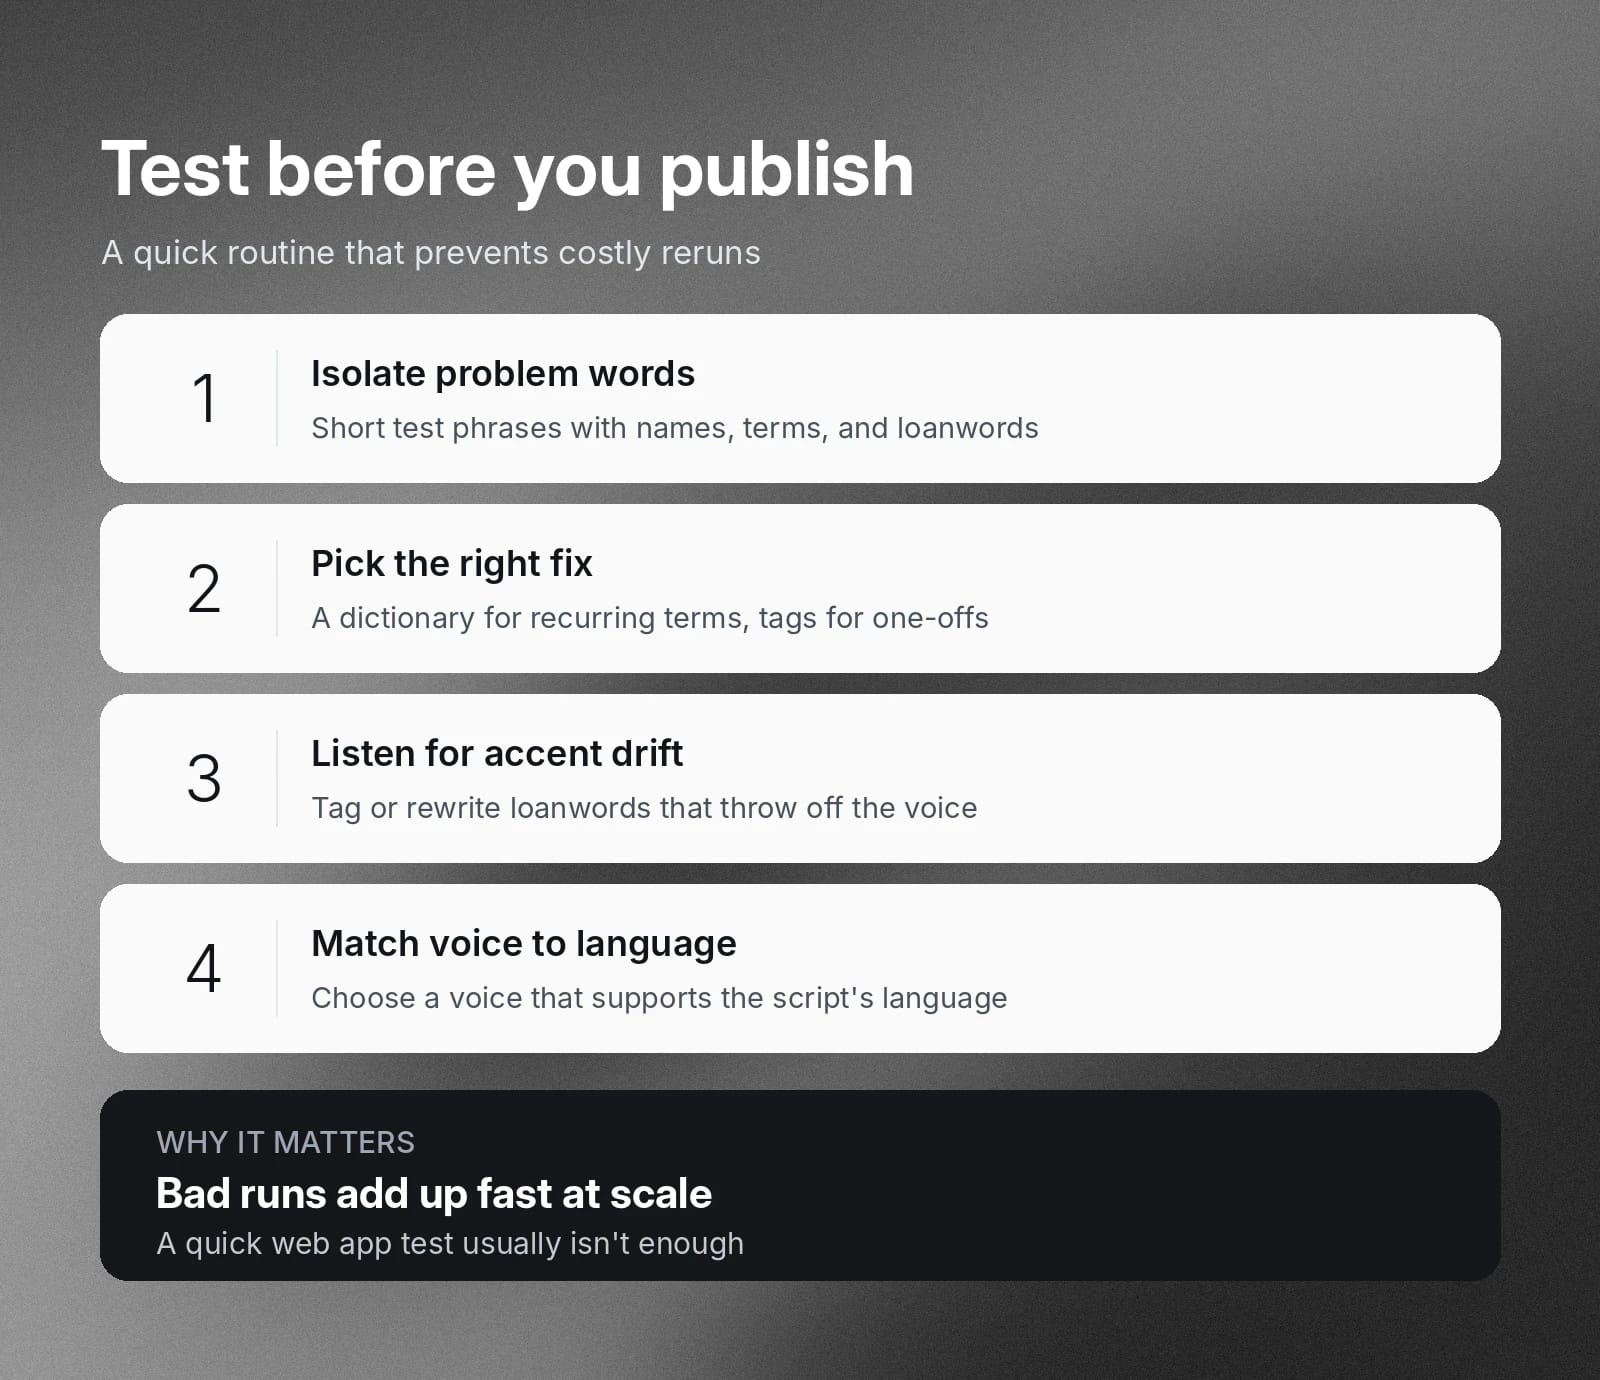
A quick web app test is usually insufficient quality control for large-scale TTS payloads. The cost of bad runs can add up quickly. Test your script in a series of controlled iterations before you submit. That upfront preparation will help you produce the highest-quality voice audio most efficiently.
Test problem words in isolation
Usually your problems will be specific passages or just specific words or names, rather than something pervasive. Create test phrases of five to ten words that contain your brand names, technical terms, or foreign language phrases. Based on the outputs, decide whether you want to use a pronunciation dictionary or just phonetic tags for each.
Identify probable language or accent drift
Speech models might occasionally adopt a strange or slow cadence mid-sentence. This often happens when the model has to guess how to pronounce a passage that differs from what it saw in training.
- Loanwords: Text using obscure loanwords from a foreign language can throw off a model's grapheme mapping, making all subsequent speech sound strangely accented. Use phonetic tags on the loan word or rewrite.
- Stilted non-English speech: A model optimized for English might stutter or sound robotic when reading a translated script. Select a voice profile that also supports the native language.
Get started with ElevenAPI for more reliable speech output
When you know what to watch for, you’ll generate high-quality voice content faster and with fewer headaches. Recognize how to handle output issues and technical API issues that might stall production.
Learn more about generating high-quality, precise TTS content with ElevenAPI or get your API key today to get started.
Frequently asked questions about text to speech issues

Jack Limebear is on the Growth team, acting as a content writer and strategist across the blog and insights pages. Before ElevenLabs, he spent over a decade leading content strategy for organizations ranging from fast-growing SaaS startups to Fortune 500 companies. He holds a Master's degree in English Literature from the University of Cambridge.