

Speech to Text API
Transcribe speech with ElevenLabs Scribe v3
Our most accurate Speech to Text model. Transcribe meetings, calls, and interviews, with speaker labels and controls for the words that matter.
- Lovable
- Veed model
- Synthesia
- Stripe
- Perplexity
- Twilio
Most accurate Speech to Text API for batch workloads
Create captions, subtitles, and editable transcripts for podcasts, videos, interviews, and other recorded content – all with industry-leading accuracy via API.
Unprecedented transcription accuracy
Scribe v3 makes 27% fewer word errors than Scribe v2 across 102 languages, and fewer than every other batch model we tested.
Designed for every scenario
Transcription that works in noisy environments, with background music, strong accents, and low-quality audio.
Fine-grained control over timing, speakers, and non-speech events.
The ElevenLabs Transcription API can detect laughter, emotion, and sound effects. Use keyterm prompting to guide transcription with domain-specific terms.
Transcribe audio and video
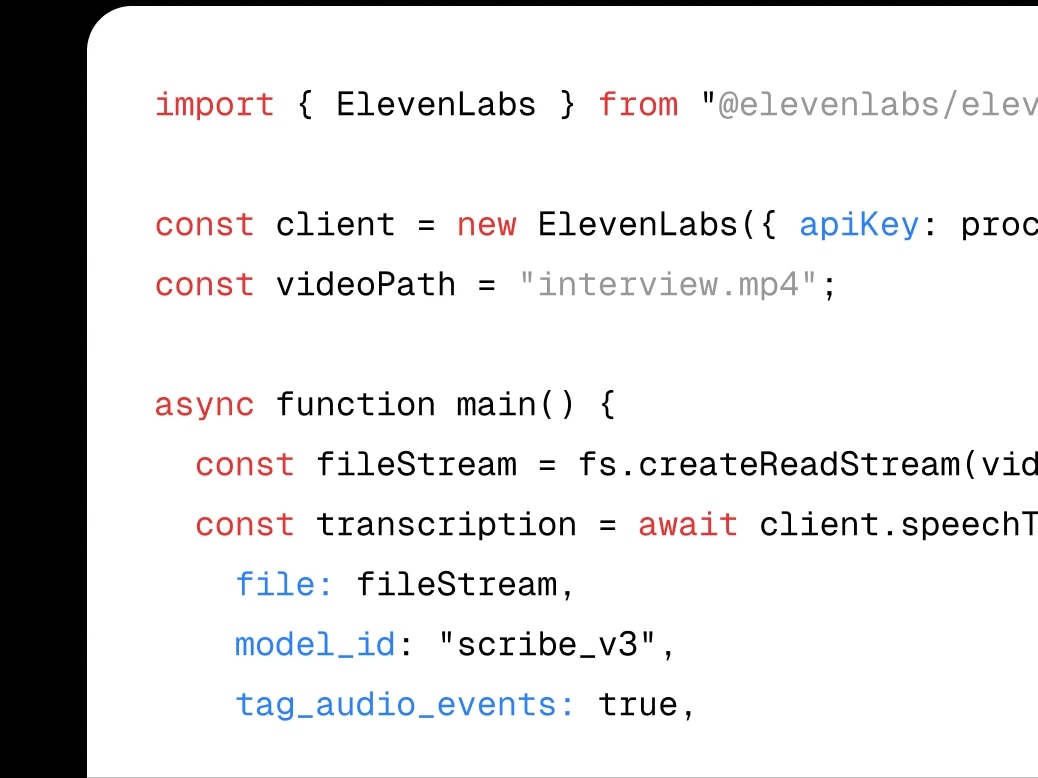
Clean, editable transcripts

Keyterm prompting

Dynamic audio tagging
Capture non-speech events like laughter, applause, music, and background noise. Transcripts include the full context of your audio, not just the words.
Smart speaker diarization
Automatically identify and label up to 32 speakers. Clear attribution of who said what, organized into readable transcripts.
Entity detection
Automatically identify and tag 56 entity types including names, dates, locations, and organizations within your transcripts.
Transcribe clinical audio with Scribe v2 Medical
A Speech to Text model optimized for medical transcription and clinical workflows, with enhanced recognition of medication names, anatomy, and pathology terms.
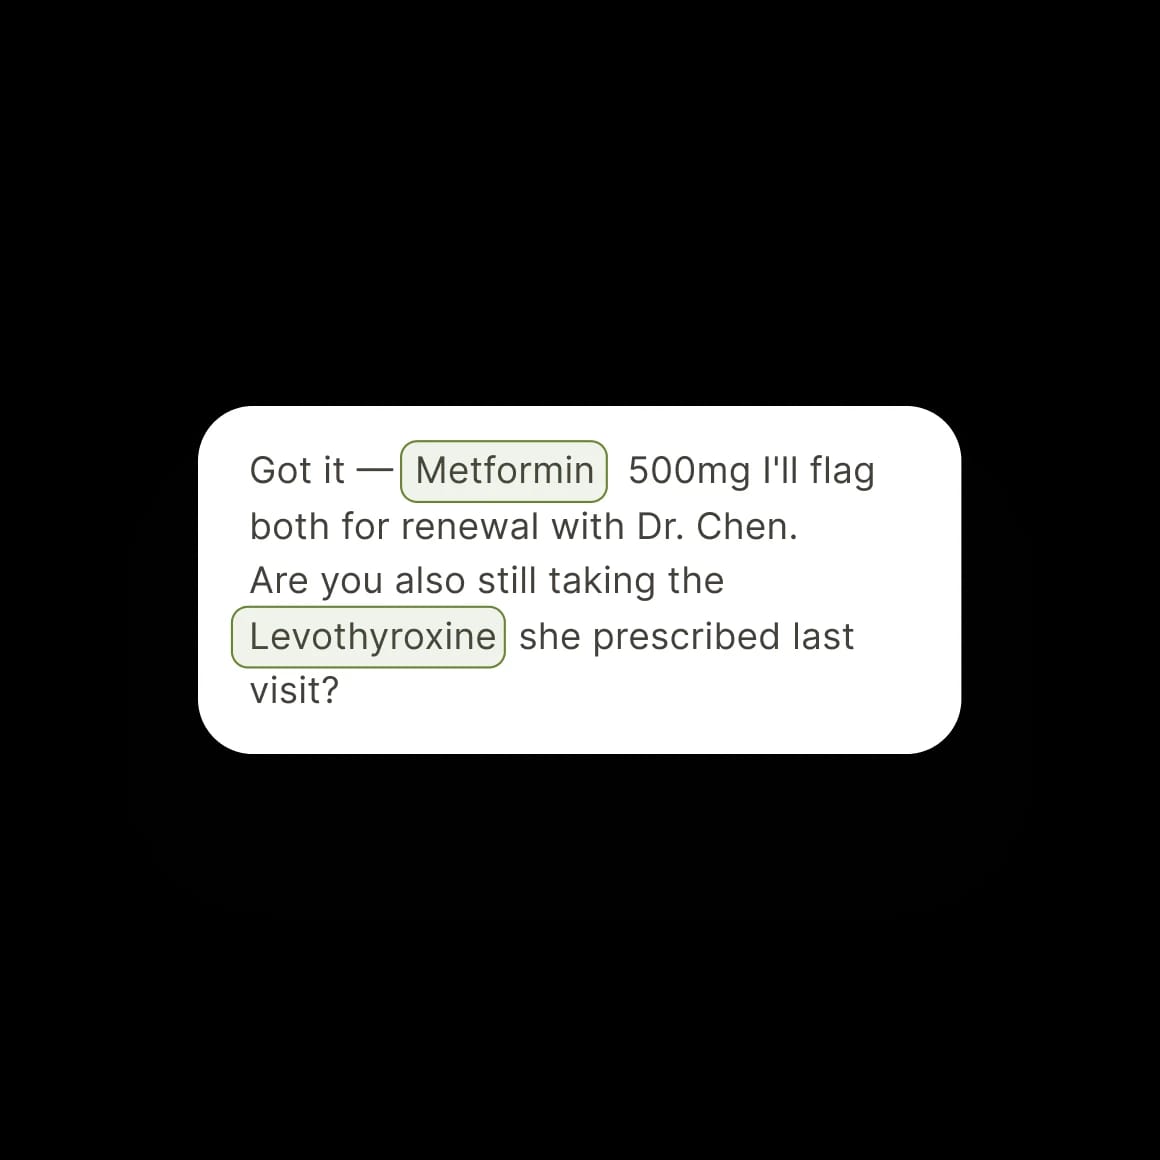
Transcribe clinical speech
Convert clinician-patient conversations, doctor dictation, and patient intake into precise text, ready for clinician review and use in notes, coding, and downstream documentation workflows.
Fewer errors on medical terms
On term-WER, Scribe v2 Medical makes 15% fewer errors than Scribe v2 on the Eka Medical ASR test split, with improved medical voice recognition across clinical vocabulary.
Scribe v3
Highest accuracy, designed for batch workloads.
- 27% fewer errors than Scribe v2
- Lowest diarization error we tested
- Number formatting and language hints
- Entity detection and keyterm prompting
- 90+ languages supported
Scribe v3 Live
Lowest latency, for realtime workloads.
- Under 150ms Latency
- 43% fewer errors than v2 Realtime
- Keyterm library and multilingual mode
- Improved turn detection
- 90+ languages supported
Scribe v2 Medical
Medical fine-tune, for clinical transcription.
- Medical Vocabulary Tuning
- Transcription in 90+ Languages
- Matches Scribe v2 on Everyday Speech
- Improved Recognition of Medication Names
- HIPAA-Eligible for Enterprise Customers
Transcribe speech in 90+ languages and a wide range of accents
Delivering exceptional accuracy across accents, dialects, and recording conditions.
Change the languageCode to preview languages
import { ElevenLabsClient } from "@elevenlabs/elevenlabs-js";
const elevenlabs = new ElevenLabsClient({
apiKey: "<your_api_key>"
});
const response = await fetch(
"https://storage.googleapis.com/eleven-public-cdn/audio/marketing/nicole.mp3"
);
const audioBlob = new Blob([await response.arrayBuffer()], { type: "audio/mp3" });
const transcription = await elevenlabs
.speechToText.convert({
file: audioBlob,
modelId: "scribe_v3",
tagAudioEvents: true,
languageCode: , // Set language
diarize: true
});
console.log(transcription);


Powering the world’s leading companies and brands
“From dubbing Reels in local languages, to generating music and character voices in Horizon, ElevenLabs platform enables global creators, businesses, and enterprises to build with voice, music, and sound at scale.”

“Scribe’s unmatched accuracy across so many languages lets Fieldy understand every daily conversation and easily scale across continents. Fieldy has increased user retention by 50% after moving to ElevenLabs Scribe.”

“ElevenLabs made it easy for us to quickly bring powerful text-to-speech capabilities to our SDK, allowing Agents to respond in real time with expressive voices to user questions or as feedback to what it’s seeing.”
“Twilio has integrated ElevenLabs’ generative AI voice technology into its CPaaS, enhancing ConversationRelay. This integration allows businesses and developers to create conversational AI voice interactions that sound human, feel expressive, and respond in real time directly from the Twilio CPaaS platform. We at ElevenLabs are excited that Twilio has chosen ElevenLabs to enhance ConversationRelay with the most expressive, human sounding voices available. ”

APIs built for production

Data is encrypted in transit and at rest, with support for SOC 2, HIPAA, and GDPR compliance. EU Data Residency and Zero Retention modes are available for stricter data control.
Data is encrypted in transit and at rest, with support for SOC 2, HIPAA, and GDPR compliance. EU Data Residency and Zero Retention modes are available for stricter data control.
Official Python and TypeScript SDKs with type safety, streaming support, and clear examples.
Our team ensures a smooth launch and keeps your operations running reliably, delivering consistent performance and peace of mind.
